Research / SSG series
System Substrate Graph (SSG)
Heterogeneous execution · Workload × System × Schedule · Operator, Model and Agent workloads
SSG studies how explicit Compute, Memory, Communication (CMC) structures represent and constrain execution across operator kernels, training/inference/RL and dynamically revealed Agent/tool/model workloads. Extending a representation does not itself prove end-to-end executability or performance.
Overview: Research Question and Scope
SSG asks whether explicit Workload, System, and Schedule structures can make otherwise fragmented AI execution decisions expressible, constrained, translatable, and experimentally testable. Its central design is a separation of workload structure, resource capabilities, legal mapping, and target-specific realization.
Scope and Evidence Boundaries
SSG now treats Agent/tool/model execution as a Workload scope, alongside operators and model training/inference/RL. The former Agent-SSG label is historical and no longer designates an independent active research line. SSG-DT is a predictive modeling direction, not the definition of the functional substrate.
A public research overview emphasizes the representation and evidence boundaries, rather than internal execution roadmaps and experimental resource plans.
Key Figures and Evidence
The figures describe the structural motivation, workload/system hierarchies, bounded strategy space, and implementation evidence from the historical manuscript. They are not evidence of unmeasured generality across all Agent workloads or accelerators.
Core Architecture: Abstract, Calibrated and Instantiated SSG
Between open frontend IRs (PyTorch FX, ONNX, Triton, StableHLO) and closed vendor backends, SSG provides a hardware-independent Schedule & Resource Orchestration IR built around three graph objects and a Build–Traverse–Translate (BTT) pipeline:
DT) and intermediate memories (IM) align structurally with hardware compute cores (CC), memory tiers (Mem), and candidate communication edges.| Stage | Graph Object | Structural Elements | Role in Pipeline |
|---|---|---|---|
| 1. Software Workload | AbstractSSG |
ComputeNode, MemoryNode (GM anchors), CommunicationEdge |
Canonical workload IR imported via cg2ssg across operators and MacroOps |
| 2. Hardware System | CalibratedSSG (Substrate) |
Node (compute/memory), Domain tree (parent__child), candidate PhysicalEdge |
Encodes hardware hierarchy capacities, legal communication primitives (lsu, cp.async, tma, nvlink), and sync scopes |
| 3. SW × HW Binding | InstantiatedSSG |
Committed per-Domain tiling, placement, pipeline stages, and selected edge_ids |
Verified legal execution plan consumed by the Backend Realizer (or SSG-DT simulator) |
Execution Semantics: CMC to CRS
CMC (Compute–Memory–Communication) describes workload/system structure before a mapping is chosen. CRS (Compute–Remap–Sync) describes the selected execution. The relationship is not a one-to-one renaming: a logical communication relation can become a local layout change, a transfer, a collective, or no materialized transfer when a realization removes the boundary.
AbstractSSG(W) and CalibratedSSG(S) are independent Build outputs. Traverse binds them with a Schedule domain by domain and chooses among the supported compute resources (which may include scalar, vector and tensor units), partitions, Remap and Sync decisions. Instantiate records that mapping; Translate realizes it with a supported backend. Hardware-specific execution templates belong at the Translate boundary, not in the shared middle representation. The System object's historical name, CalibratedSSG, does not imply digital-twin timing calibration.
Schedule as Parallel × Pipeline
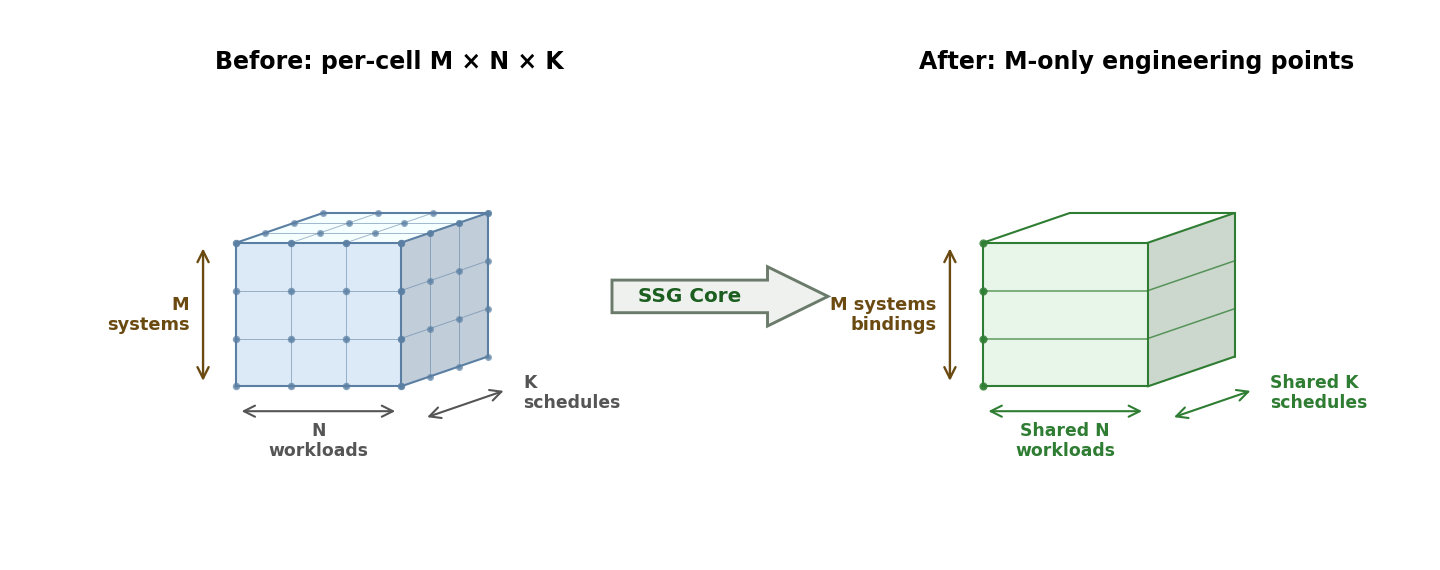
The lean-framing working draft organizes Schedule into Parallel (partitioning, replication, ownership, and placement) and Pipeline (staging, ordering, buffering, and overlap). DP/TP/EP/FSDP and PP/1F1B are specific projections or compositions within those families. The schematic M × N × K authoring surface motivates reuse across hardware, workloads, and strategies; it is not a proved asymptotic complexity reduction.
Compute tiling semantics separate Input Partializability, Output Finalization, and Ordering Constraint (IPOFOC). Compute–compute fusion needs compatible partitions, finalization, and ordering. Compute–Remap fusion additionally depends on the selected execution and target capabilities. Remap requirements can originate in workload communication, hardware layout adaptation, or mapping/execution boundaries.
Workload Scope: Operators, Models, and Agents
| Workload scope | Execution question | Evidence |
|---|---|---|
| Operator / Subgraph | Tiling, compute-unit selection, fusion and memory movement | Bounded H20 operator experiments in the September manuscript |
| Model / Trainfer | Training, inference and RL scheduling and model-subgraph execution | Selected 8×A800 framework experiments in the September manuscript |
| Agent / Tool / Model | Dynamically revealed tasks, CPU tool calls, model invocation and traceable cross-layer dispatch | Integrated SSG research direction; new end-to-end measurements pending |
The earlier Agent-SSG name is retained only for historical provenance; its execution scope is now part of SSG, not an independent graph formalism or paper. Dynamic workloads require explicit dependencies, effects and execution witnesses. No Agent speedup is inherited from earlier operator/model measurements.
The SSG-DT extension develops prediction and hardware/software what-if analyses over supported SSG execution plans. Its results remain unvalidated at the general level. TSG remains an independent task-world research line.
Evaluation Groups in Paper 1 (Sep-V2.4.7)
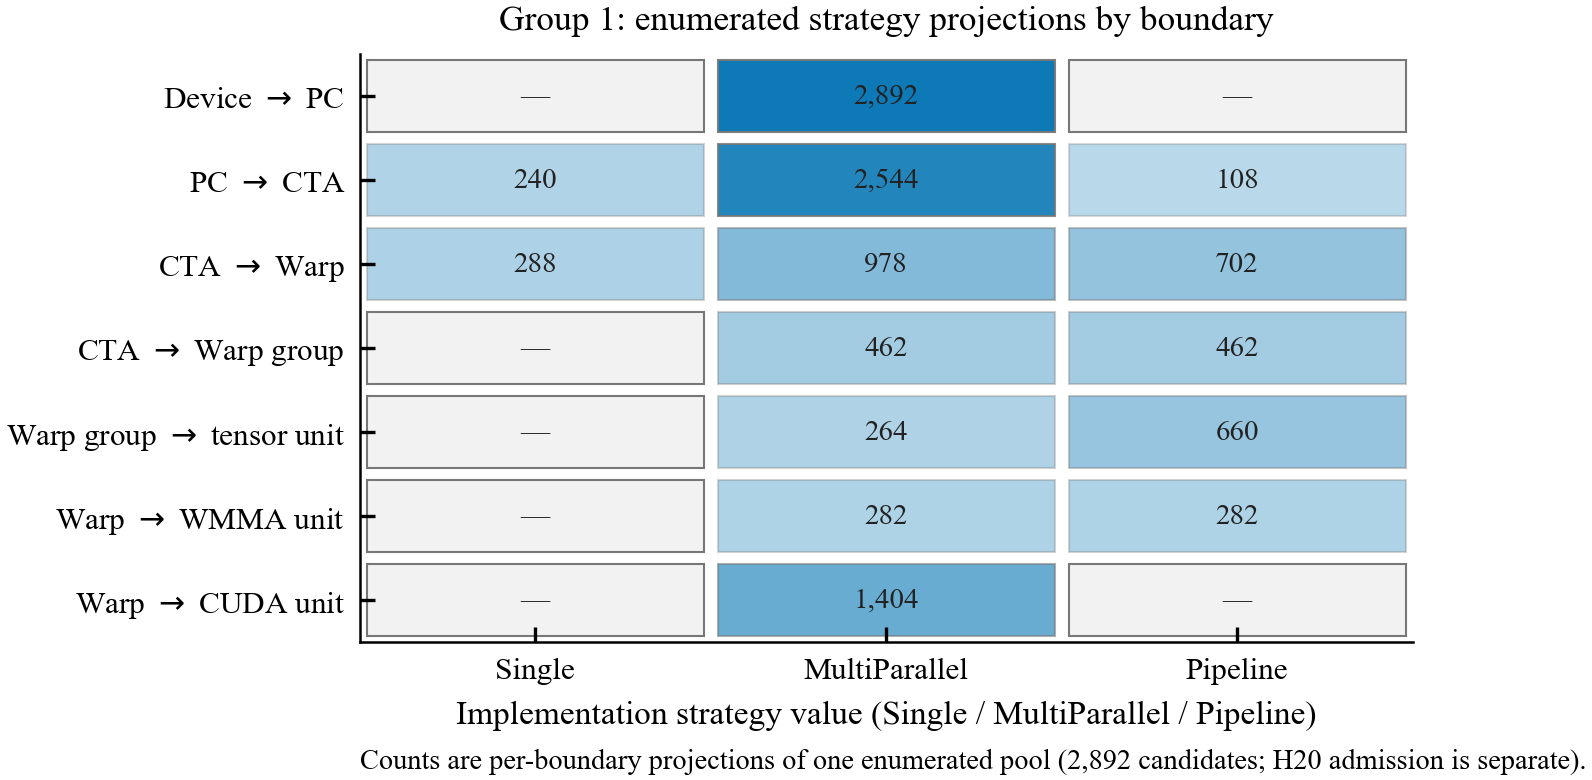
- Group 1 (Intra-Device Operators): Bounded enumeration, legality filtering, and CUDA/Triton realization for GEMM on NVIDIA H20.
- Group 2 (Trainfer framework experiments): The attached submission reports selected DP/TP/PP and prefill/decode studies on A800. Representational coverage of training/inference/RL does not establish every scale-out or RL execution path as physically validated.
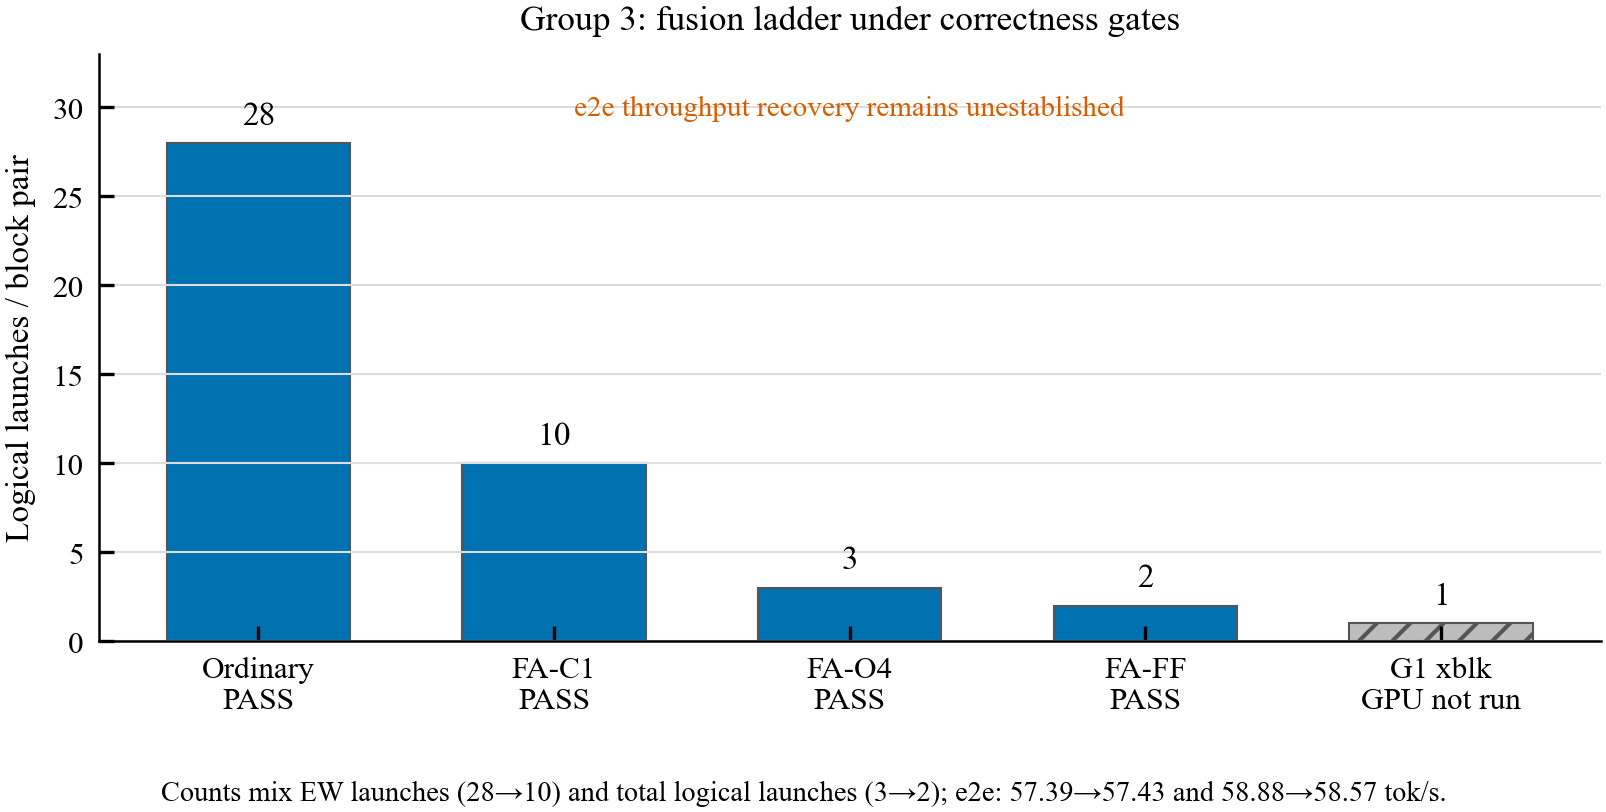
- Group 3 (Composite Model Subgraphs): Multi-operator GQA producer/consumer chains and MoE routing/expert execution paths, plus RS-DSA capability-profile discussion (Appendix B), distinct from measured cross-hardware portability.
Measured Results
Numbers reported in the September 2026 technical manuscript (§5–7). They cover single-node H20 and 8×A800 configurations only.
| Scope | Result | How to read it |
|---|---|---|
| Operator: GEMM (H20) | 2,892–2,988 legal candidates per shape; generated kernels reach 49.6–110.1% of cuBLAS on nine FP16 shapes, elementwise identical to the reference | Best-in-pool per shape, not automatic selection |
| Operator: correctness funnel | 194 of 482 measured variants (40.2%) fail correctness; 77 pipelined variants fail while their 77 parallel pairs pass | Legality and correctness are reported as separate stages |
| Operator: row reduction | 1.09–2.79× CUB throughput on all 66 declared cases | Mostly from one fused launch vs. two library launches |
| Framework: inference (8×A800) | Qwen3-8B at offered load 512: DP4×TP2 reaches 7,781 tok/s, +57% over TP8 | The best binding moves with load; one Schedule vocabulary covers DP/TP/PP |
| Framework: transport | PP2×TP4 vs. TP8 ratio spans 0.59–1.03 on NVLink and 0.86–3.40 with P2P disabled (Qwen3-8B) | The preferred binding also moves with the System input |
| Framework: training / RL | SFT scales 1.316× from 4 to 8 devices (65.8% efficiency); two RL resource partitions give 13.05 s and 22.32 s step times | Plans emitted to framework-native execution |
| Model path: Qwen3 MoE | A mixed execution configuration records 205.0 tok/s, 95.6% of framework decode throughput, with substantially slower prefill | Graph capture records 48 fallbacks, so decode replay can use the framework implementation. This measures the mixed configuration, not isolated SSG-router throughput or an end-to-end speedup |
Full Paper and Versions
The new first page identifies the author, without institutional affiliation; pages 2–14 preserve the original anonymous September 2026 technical manuscript unchanged. The additional cover is not a revised experiment or a peer-reviewed publication. The original 13-page anonymous PDF remains in the private source repository, rather than being shipped as a second public paper.
Manuscript Scope and Status
System Substrate Graph: One Cross-Scale Representation of Workload, System, and Schedule for AI Computing
- Status: September 2026 technical manuscript (Sep-V2.4.7), not peer-reviewed; later research content is kept distinct from this historical snapshot.
- Public PDF: Author Web Edition — full technical report (14 pages, including the new cover).
- Claim Modality: Attainability and structural coverage, not universal superiority over hand-tuned vendor libraries. Calibrated runtime prediction and hardware co-design are explicitly scoped to SSG-DT.
Version History
2026-11-16 — SSG Author Web Edition (PDF): attribution cover plus unchanged original body, not a new scientific version.
| Date | Version Tag | Artifact / Snapshot | Substantive Changes & Provenance |
|---|---|---|---|
| 2026-09-14 | Sep-V2.4.7 |
Private anonymous historical PDF | Historical manuscript: revised introduction, G1–G3 measured figures (H20 and A800), RS-DSA appendix. |
| 2026-08-29 | Aug-V4.3.2 |
Internal draft | Terminology alignment, wording audit of unmeasured claims, paired Workload–System diagrams. |
| 2026-08-18 | Aug-V3.0 |
Internal draft | First measured experiment figures; unified AbstractSSG / CalibratedSSG / InstantiatedSSG terminology. |
| 2026-08-17 | Aug-V2.4.3 |
Internal draft | First complete ACM-format build; related work including TAOT, CUDA Tile IR, and CuTe. |
| 2026-08-06 | Roadmap v1.5.2 |
Research plan | Three-axis research space (scope × model capability × engineering maturity), staged waves, measurement kept separate from simulation. |